Bridging the GAP between
Computer Vision and Generative AI
We work on problems we find genuinely interesting in Computer Vision and Generative AI for both generation and perception and their intersection.
Research Areas

Diffusion Models & Generative Synthesis
Controllable image and video generation with diffusion models — from fine-grained, part-level editing to consistent character animation and 3D-aware scene layout.

Multi-Modal LLMs & Agentic Systems
Vision-language models and agentic pipelines that reason over images, diagrams and video — not just generate text — and act on that reasoning.
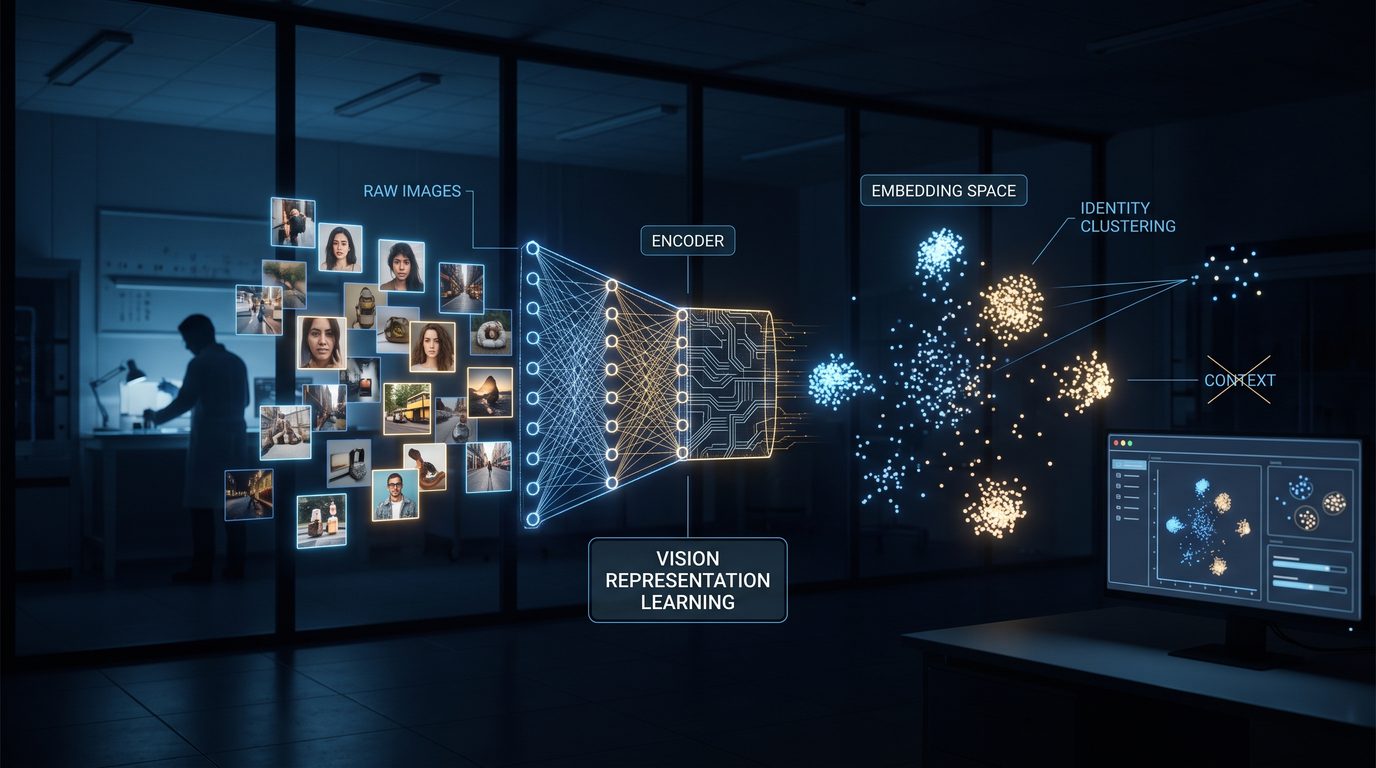
Vision Representation Learning
Learning visual embeddings that capture what actually matters — identity, semantics, and editing intent — instead of entangling it with background context or surface appearance.

3D Vision & Scene Understanding
Shape correspondence, keypoint reasoning, and language-guided object placement in real 3D scenes — connecting geometric understanding with natural-language interaction.

Uncertainty-Aware Perception
Confidence-propagating networks for sparse and noisy data — depth completion, optical flow, and regression tasks where knowing what the model doesn't know matters.

Detection, Tracking & Video Segmentation
Robust object detection, tracking and segmentation in real video — including distractor-aware tracking and zero-shot segmentation built on pre-trained diffusion models.
Publications
2026
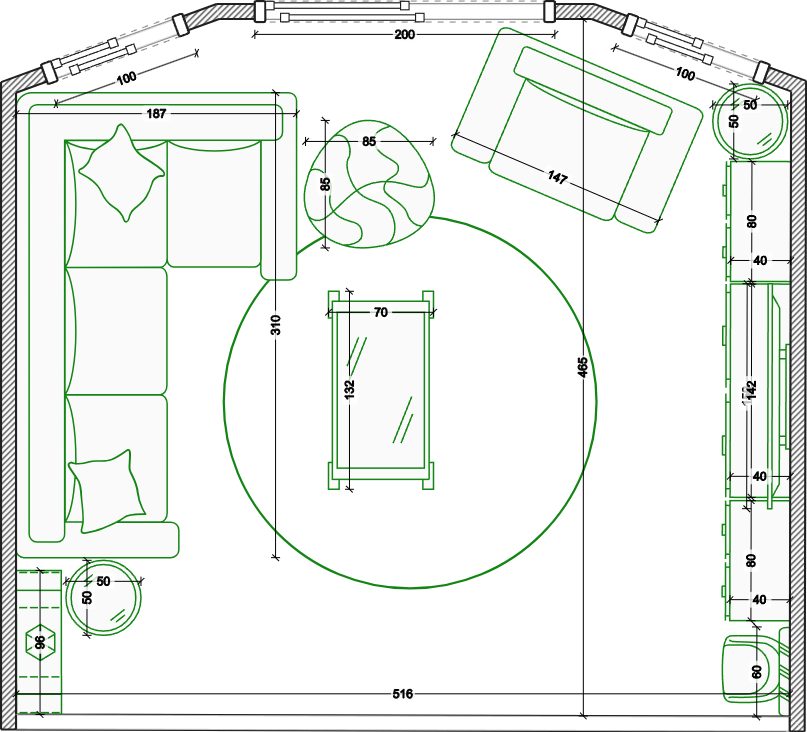
FloorplanQA: A Benchmark for Spatial Reasoning in LLMs using Structured Representations
A diagnostic benchmark for spatial reasoning in LLMs, built on structured JSON/XML representations of indoor scenes and covering tasks like distanc…
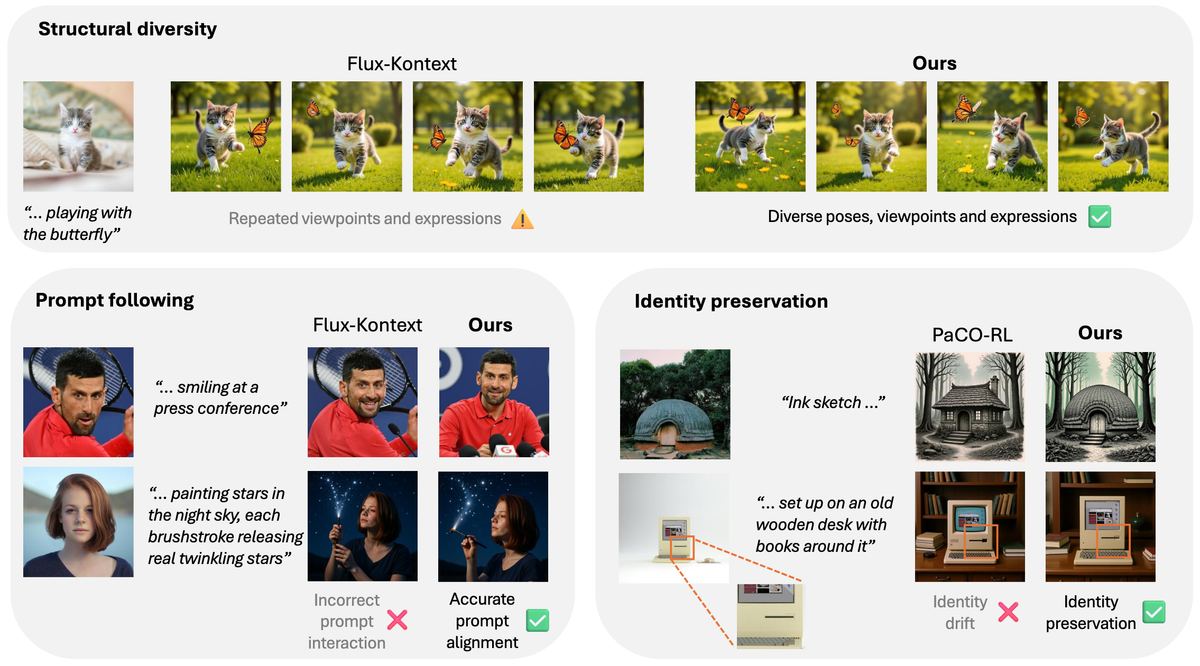
DivRL: Disentangled Self-Similarity Rewards for Diverse Subject-Driven Generation
A post-training framework for subject-driven image generation that optimizes structural diversity and identity consistency together, treating ident…
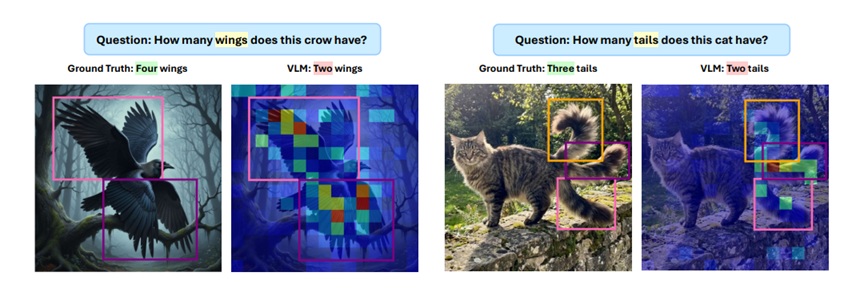
CounterCount: A Diagnostic Framework for Counting Bias in Vision Language Models
Tests whether vision-language models actually look at the image when counting objects, using paired factual/counterfactual images with edited count…
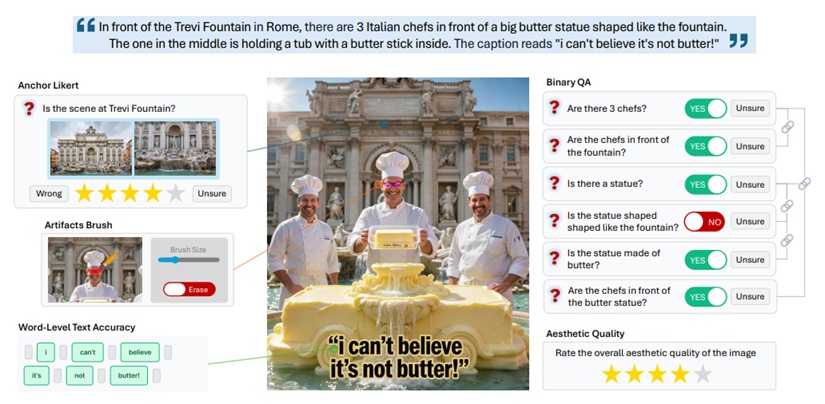
Skill-Aligned Annotation for Reliable Evaluation in Text-to-Image Generation
Proposes matching each text-to-image evaluation skill (e.g. counting, spatial relations, attribute binding) to an annotation strategy suited to its…
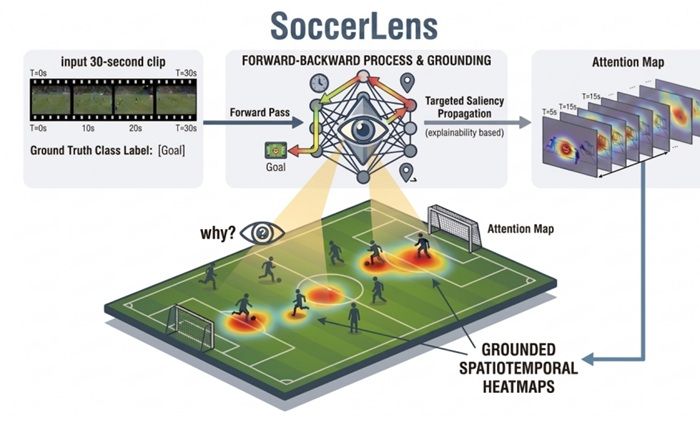
SoccerLens: Grounded Soccer Video Understanding Beyond Accuracy
Introduces a benchmark for whether soccer-video VLMs are actually grounded in what's on screen, not just pattern-matching to the right event label.…
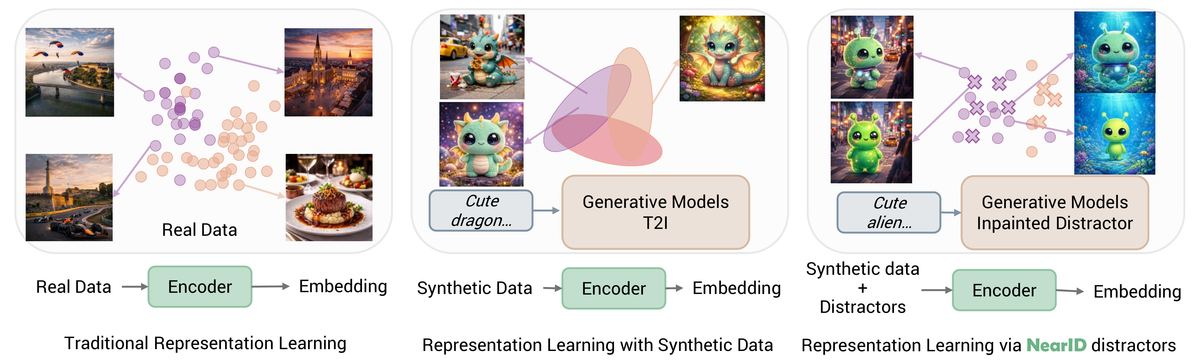
NearID: Identity Representation Learning via Near-Identity Distractors
Trains identity-aware visual representations by contrasting each identity against visually similar but distinct "near-identity" instances, separati…
2025
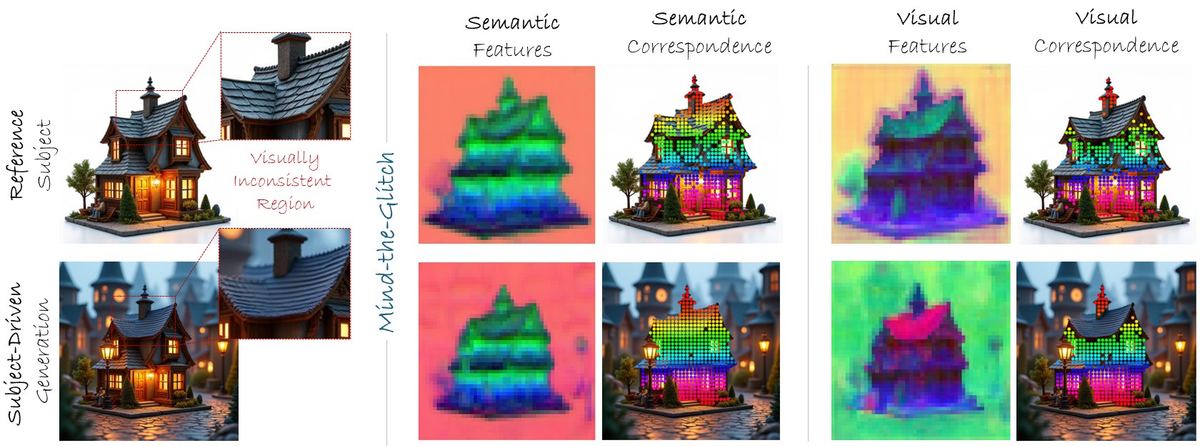
Mind-the-Glitch: Visual Correspondence for Detecting Inconsistencies in Subject-Driven Generation
Introduces a method for detecting visual inconsistencies in subject-driven image generation by leveraging visual correspondence, improving reliabil…
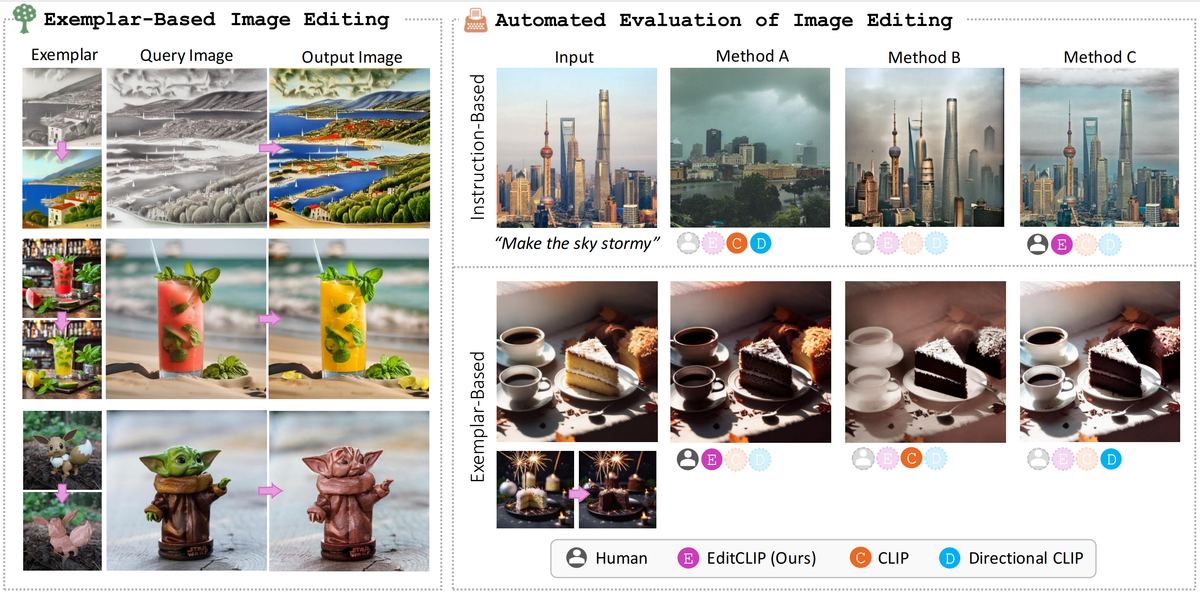
EditCLIP: Representation Learning for Image Editing
A representation-learning approach tailored to image editing, learning embeddings that capture the semantics of an edit itself rather than just ima…
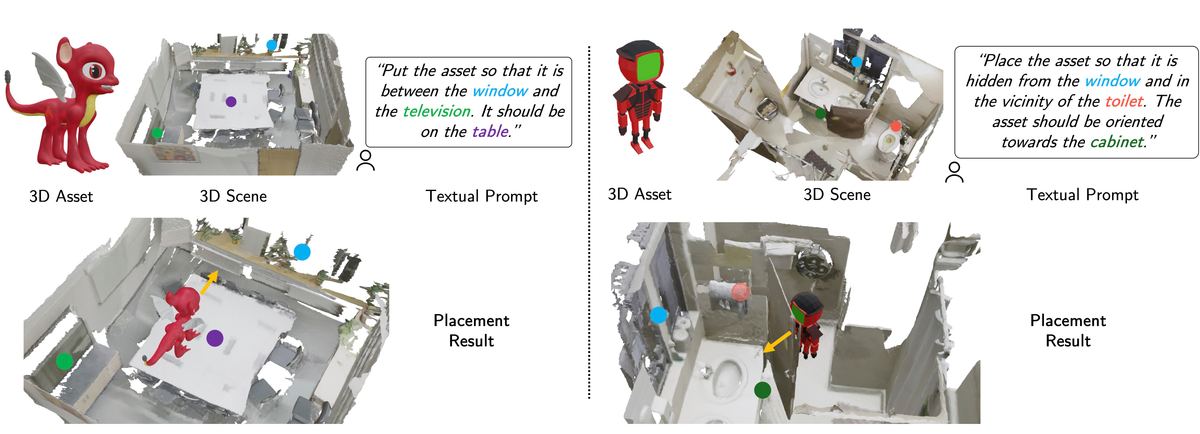
PlaceIt3D: Language-Guided Object Placement in Real 3D Scenes
Enables placing objects into real 3D scenes using natural-language instructions, bridging language understanding with geometric scene reasoning.
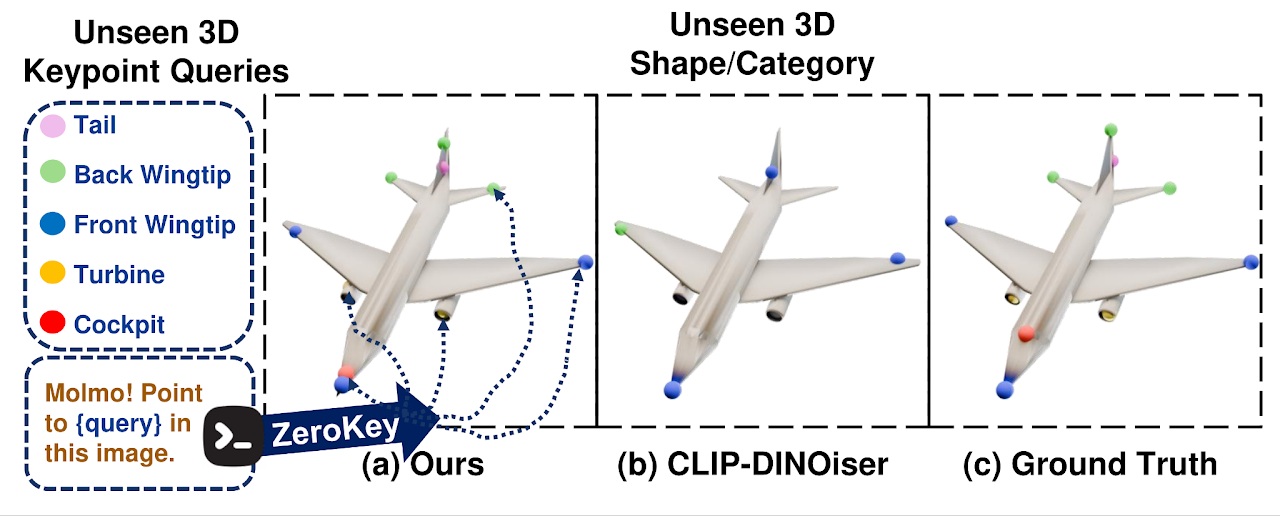
ZeroKey: Point-Level Reasoning and Zero-Shot 3D Keypoint Detection from Large Language Models
Shows that large language models can be used for zero-shot, point-level reasoning to detect semantic 3D keypoints without task-specific training da…
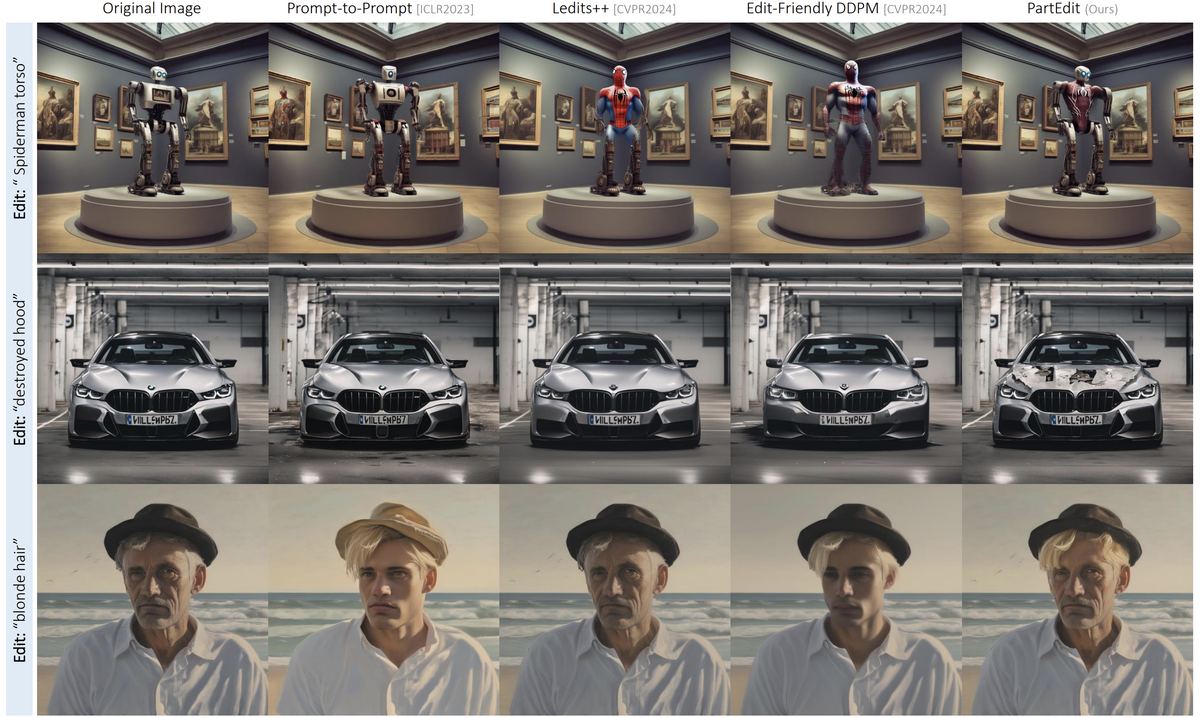
PartEdit: Fine-Grained Image Editing using Pre-Trained Diffusion Models
A method for precise, part-level image editing built on pre-trained diffusion models, allowing targeted edits to specific object parts without dist…
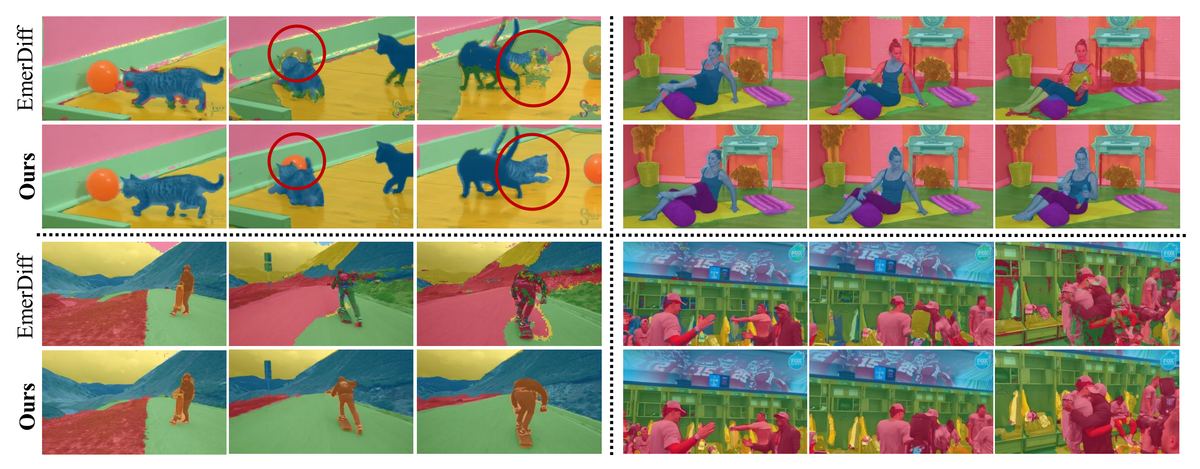
VidSeg: Zero-Shot Video Semantic Segmentation based on Pre-Trained Diffusion Models
Repurposes pre-trained diffusion models for zero-shot semantic segmentation of video, removing the need for task-specific labeled training data.
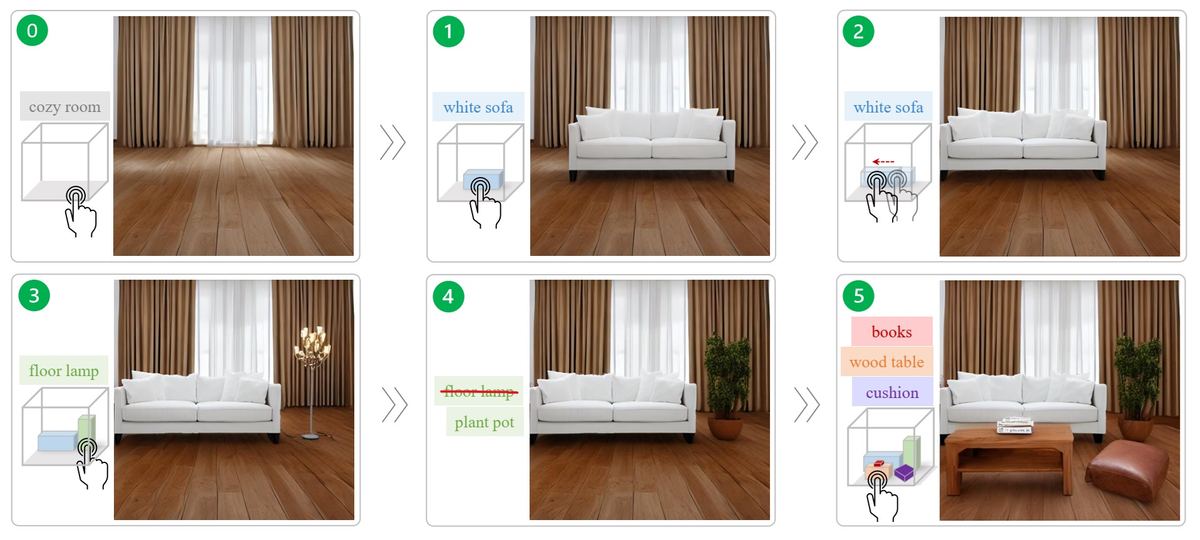
Build-A-Scene: Interactive 3D Layout Control for Diffusion-Based Image Generation
Gives users interactive, explicit control over 3D object layout when generating images with diffusion models, closing the gap between free-form pro…
2024
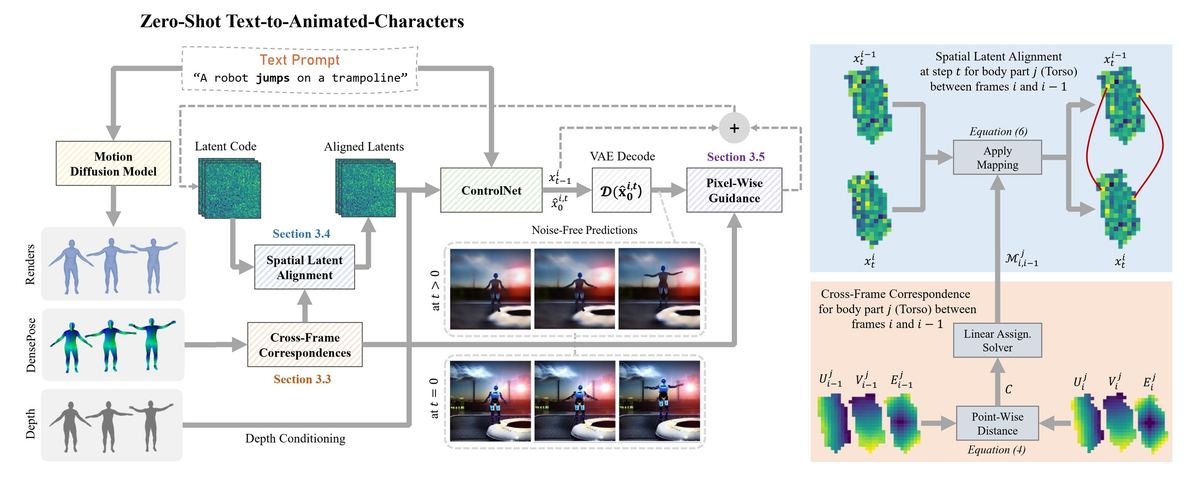
LatentMan: Generating Consistent Animated Characters using Image Diffusion Models
Generates animated characters that stay visually consistent across frames using image diffusion models, addressing a core weakness of frame-by-fram…
Estimating Multimodal Aleatoric Uncertainty in Regression Tasks
Proposes a method for estimating multimodal aleatoric uncertainty in regression problems, extending prior uncertainty-estimation work beyond single…
2021
Distractor-Aware Video Object Segmentation
Improves video object segmentation robustness by explicitly modeling visually similar "distractor" objects that commonly cause tracking and segment…
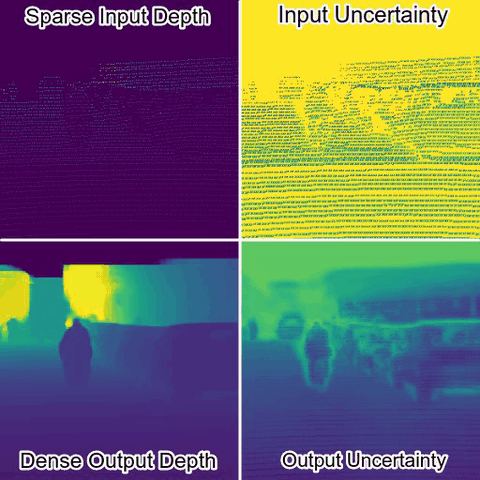
Uncertainty-Aware CNNs for Depth Completion: Uncertainty from Beginning to End
Introduces a depth-completion approach that propagates uncertainty estimates end-to-end through the network, improving reliability of depth predict…
Normalized Convolution Upsampling for Refined Optical Flow Estimation
Presents a normalized-convolution-based upsampling technique that refines optical flow estimates, improving accuracy at object boundaries and in sp…