← All publications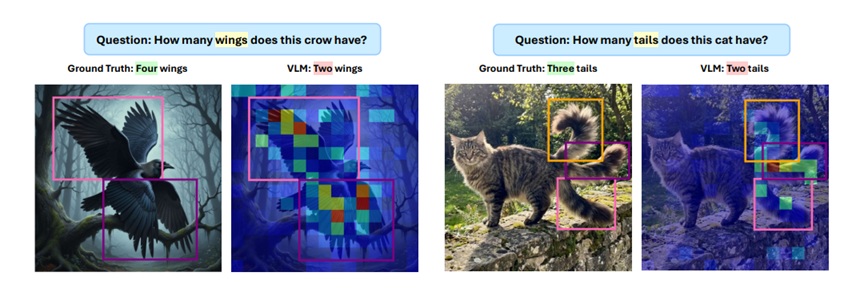
CounterCount: A Diagnostic Framework for Counting Bias in Vision Language Models
Abstract
Tests whether vision-language models actually look at the image when counting objects, using paired factual/counterfactual images with edited counts and localized evidence annotations. Models do well on factual images but degrade under counterfactual edits, revealing reliance on learned object-count priors — traced to underweighted attention on count-relevant visual tokens, which an inference-time attention-reweighting strategy partially corrects.