← All publications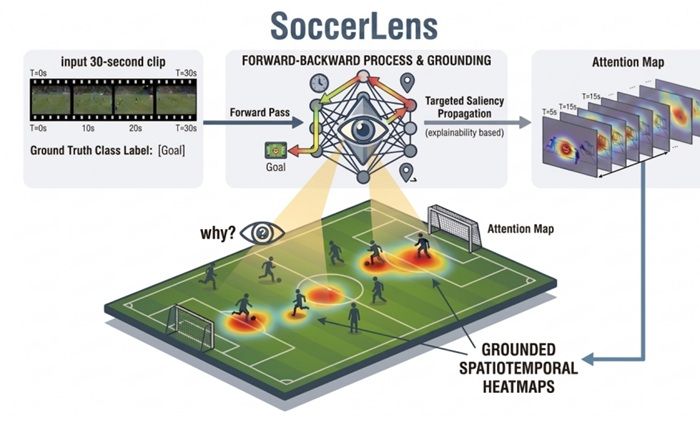
SoccerLens: Grounded Soccer Video Understanding Beyond Accuracy
Abstract
Introduces a benchmark for whether soccer-video VLMs are actually grounded in what's on screen, not just pattern-matching to the right event label. Annotates soccer clips across 13 event types with layered visual cues and extends spatio-temporal attribution methods to score attention alignment. Finds that even accurate models rarely exceed 50% grounding and consistently underuse temporal information — accuracy and true visual grounding diverge.